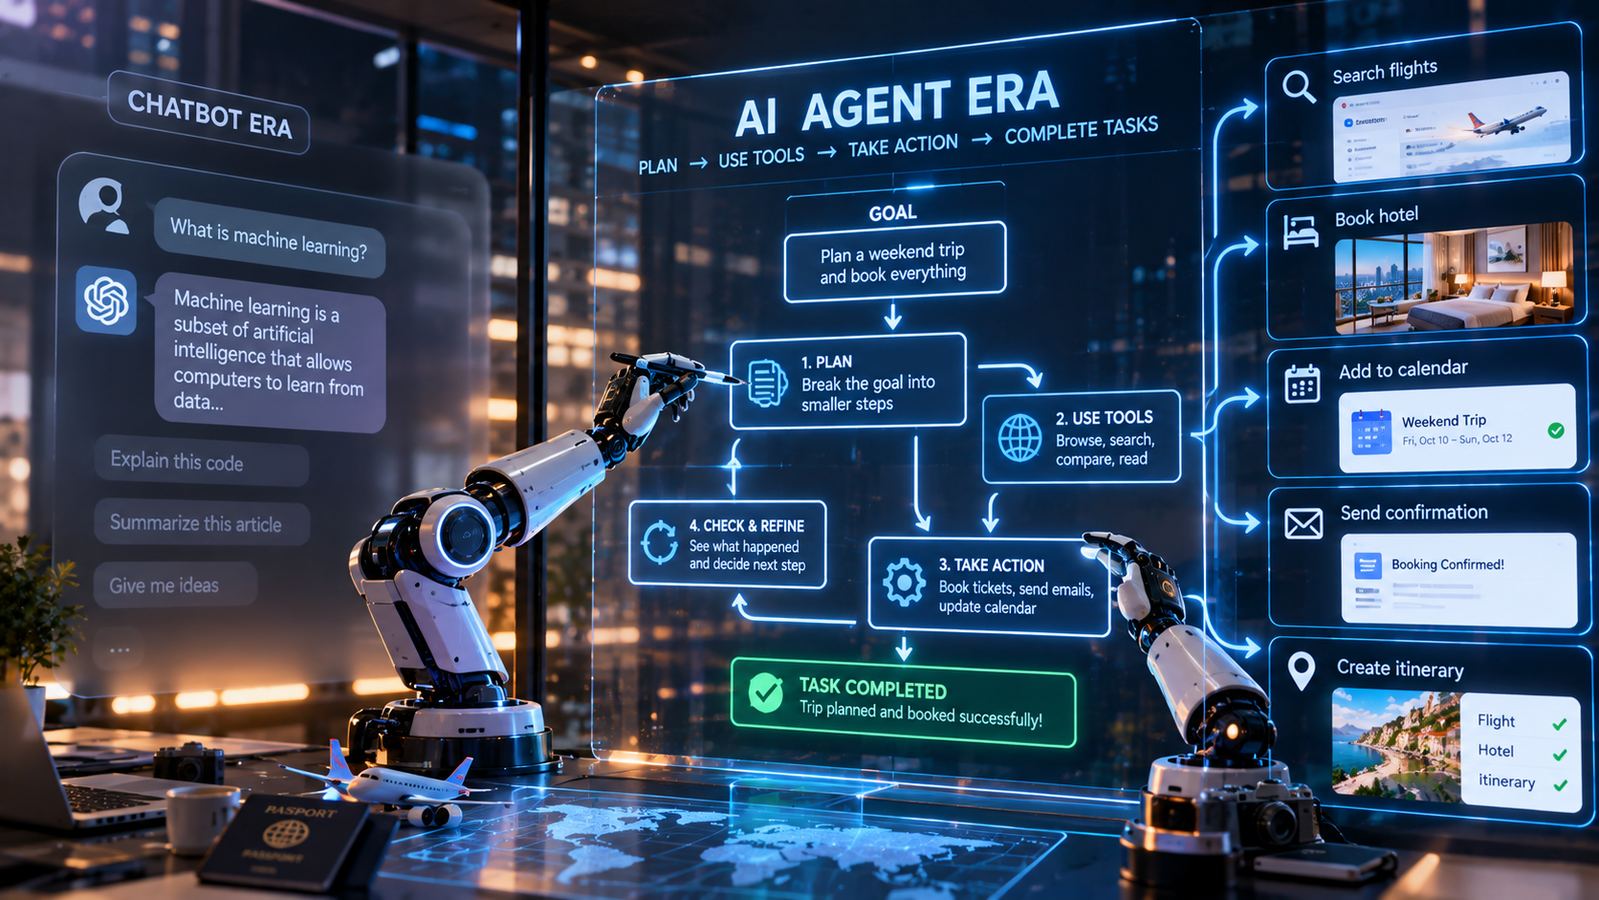
For the last three years, AI mostly meant one thing: a text box. You typed a question, and it typed back an answer. That is starting to change. OpenAI, Anthropic, Google DeepMind, and a wave of startups are now racing to build "agents" — AI systems that don't just reply to you. They plan out steps, use tools like a browser or a code editor, and try to finish a task on their own.
This matters because it changes what you're actually handing over to an AI. A chatbot can only give you words back. An agent can send an email, spend money, delete a file, or push code to production. That is a much bigger deal if it gets something wrong. The shift is real, and it is moving fast — but it is also messier than the demo videos make it look.
From Answering to Doing
Here is the basic idea behind an AI agent. The model looks at your goal and breaks it into smaller steps. Then it picks a tool — maybe a web browser, a code editor, a file, or an app — and takes an action. It checks what happened, and decides what to do next. This loop repeats until the task is done. Researchers built the first versions of this idea back in 2022, with methods called ReAct and Reflexion. Companies have since turned it into real products.
Anthropic's Claude can now take a screenshot of your screen, then move the mouse, click, and type, almost like a person using a computer. Anthropic says this "computer use" feature now hits around 88% reliability on well-structured tasks in its own tests — though Anthropic's own leadership has been upfront that early on, this kind of accuracy was still below what most people would expect from a human assistant. OpenAI's Codex can run coding tasks by itself inside a private cloud space, editing files and running tests without you watching. Google DeepMind built Project Mariner, an agent that could browse the web using Gemini.
Here is something worth noticing: several of the biggest agent products have already been shut down or absorbed into something else. OpenAI killed off Operator, its first browser agent, in under seven months. Its replacement, "ChatGPT agent," was later pulled too, in August 2026. Reports this year say Google has quietly wound down Project Mariner as its own product and folded the browser skill into a wider Gemini agent system. Why does this matter? It shows these companies keep building a flashy agent, discovering it isn't reliable enough to stand on its own yet, and pulling it back in to rework it. That's not the industry giving up. It is a sign that the hard part isn't teaching AI to plan — it's making that plan trustworthy enough to leave alone.
How Much Progress Have We Actually Made?
The best data we have comes from METR, a nonprofit that tests AI models. They measure how long a task would take a human expert, then check how often an AI agent can finish that same task. This is called the "time horizon." Since 2019, the length of tasks an AI agent can reliably finish has doubled roughly every seven months. METR says this pace sped up to about every four months between 2024 and 2025. By early 2026, Claude Opus 4.6 could reportedly handle tasks that would take a human around 12 hours. But METR is honest about the uncertainty here — their estimate for Opus 4.6 could actually be anywhere from about 5 hours to 65 hours, because there simply aren't many long, real-world tasks to test against yet.
This is the trend everyone in the industry is watching, because if it keeps holding, it means AI agents could handle week-long or month-long projects within a few years. But that gap between a smooth chart and messy real life shows up everywhere once you leave the lab. One 2026 industry report found a roughly 37-point gap between how well agents score on benchmarks and how well they actually perform once deployed in the real world. Scale AI tested agents on real freelance-style jobs and found most of them failed. And Gartner predicts that 40% of agentic AI projects will be dropped by 2027. This is usually not because the AI itself is dumb. It is because companies underestimate how hard it is to make an agent's actions safe, checkable, and repeatable outside a nice, clean demo.
What Needs to Change Next
The fixes that engineers are working on right now are not exciting, but they matter a lot. Agents need memory that sticks around across sessions, instead of forgetting everything each time. They need safe, sandboxed spaces to work in, so a mistake doesn't break something real. They need checkpoints where a human has to approve risky actions, like spending money or sending an email. And they need better ways to check whether a task was actually done right, instead of just trusting the agent's own report that it's finished.
One real step toward this happened in December 2025, when Anthropic handed over its Model Context Protocol — a shared standard for how agents connect to outside tools and data — to a new group called the Agentic AI Foundation, run under the Linux Foundation. OpenAI, Google, Microsoft, and Amazon are all backing it too. Think of it as a common road system that lets agents from different companies move between the same tools, instead of every company building its own private roads. This kind of shared standard matters because it means the winner of the agent race won't be decided purely by who has the smartest model — it will also depend on whose agents can safely plug into everything else.
The bigger promise — that AI agents will soon handle messy, multi-day projects almost entirely on their own — is still just a guess. It relies on stretching out a trend line that has already sped up once, and nobody knows if it will keep speeding up, slow down, or level off. What we know for sure right now is smaller: agents can handle clear, narrow tasks, like migrating some code or filling out a form, as long as someone is keeping an eye on them. What we don't know yet is whether they can handle long, unclear, high-stakes work with no one watching. If that gap closes, it won't just change how software gets built — it could change what jobs look like for a lot of people who currently do that kind of step-by-step, judgment-based work. That gap between the two is really what this whole race is about.