Reading the Gel: What OpenAI’s BioBasicsBench Says About AI Agents in the Lab
OpenAI’s BioBasicsBench tests AI agents on reading raw wet-lab data, revealing both multimodal gains and serious reasoning limits.
Are you sure you want to remove your upvote for this article?
Tracking the latest breakthroughs, research, and deep-tech innovations.
OpenAI’s BioBasicsBench tests AI agents on reading raw wet-lab data, revealing both multimodal gains and serious reasoning limits.
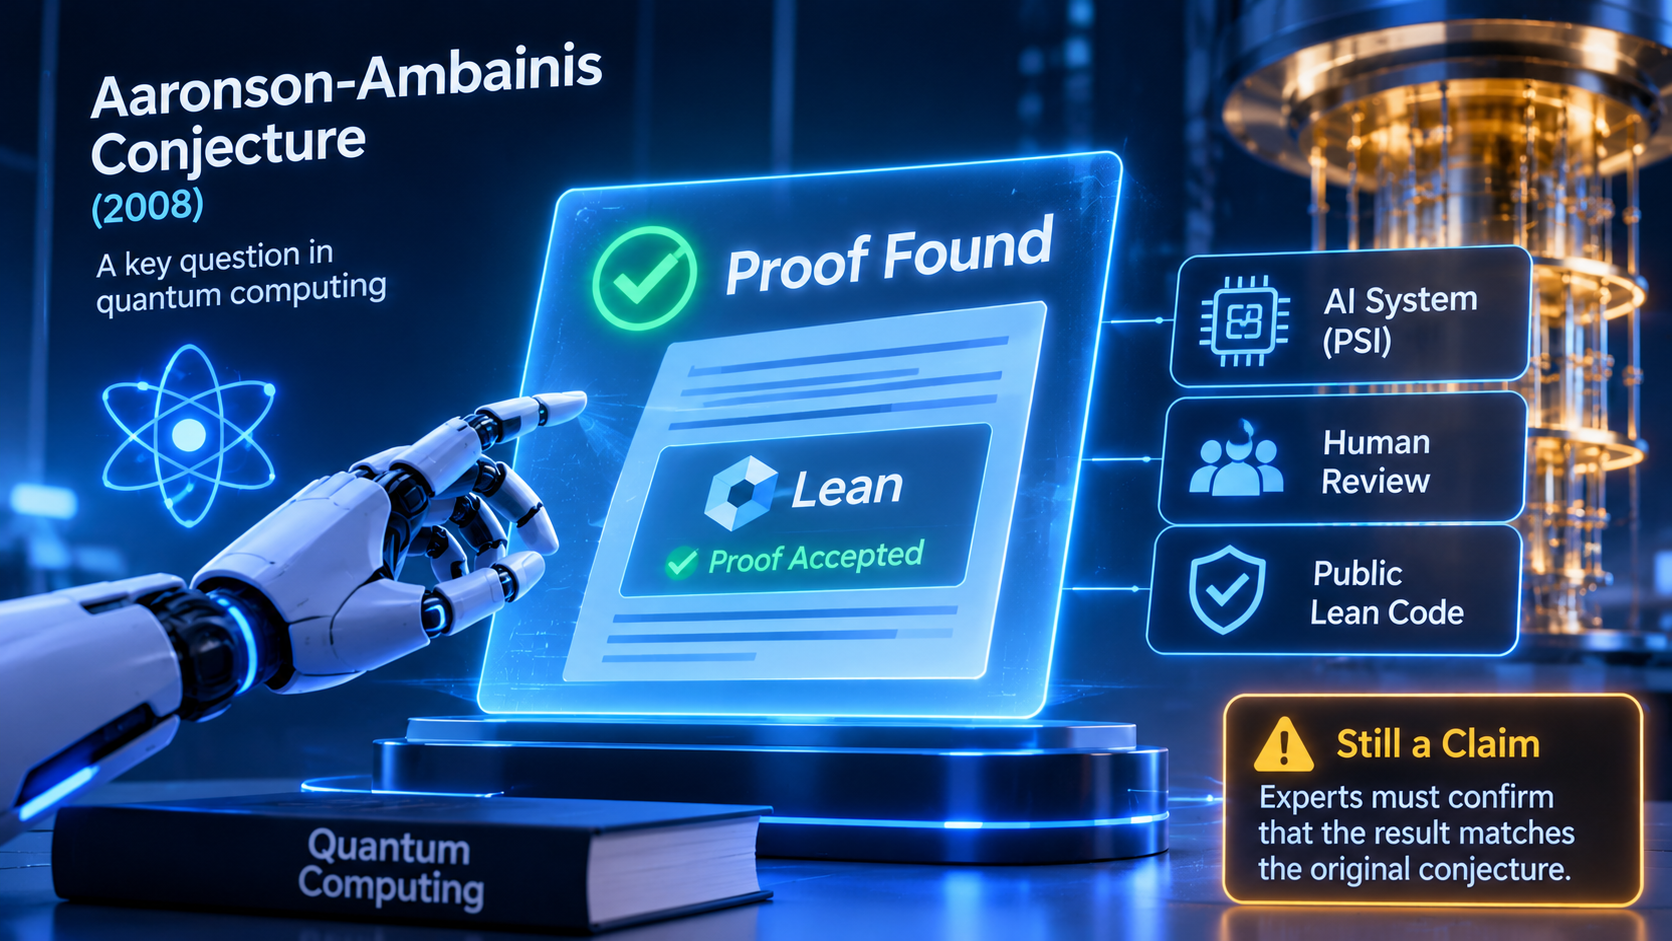
Physical Superintelligence claims a non-public Anthropic model proved the Aaronson-Ambainis conjecture. The Lean artifact is public, but the generation process remains opaque.
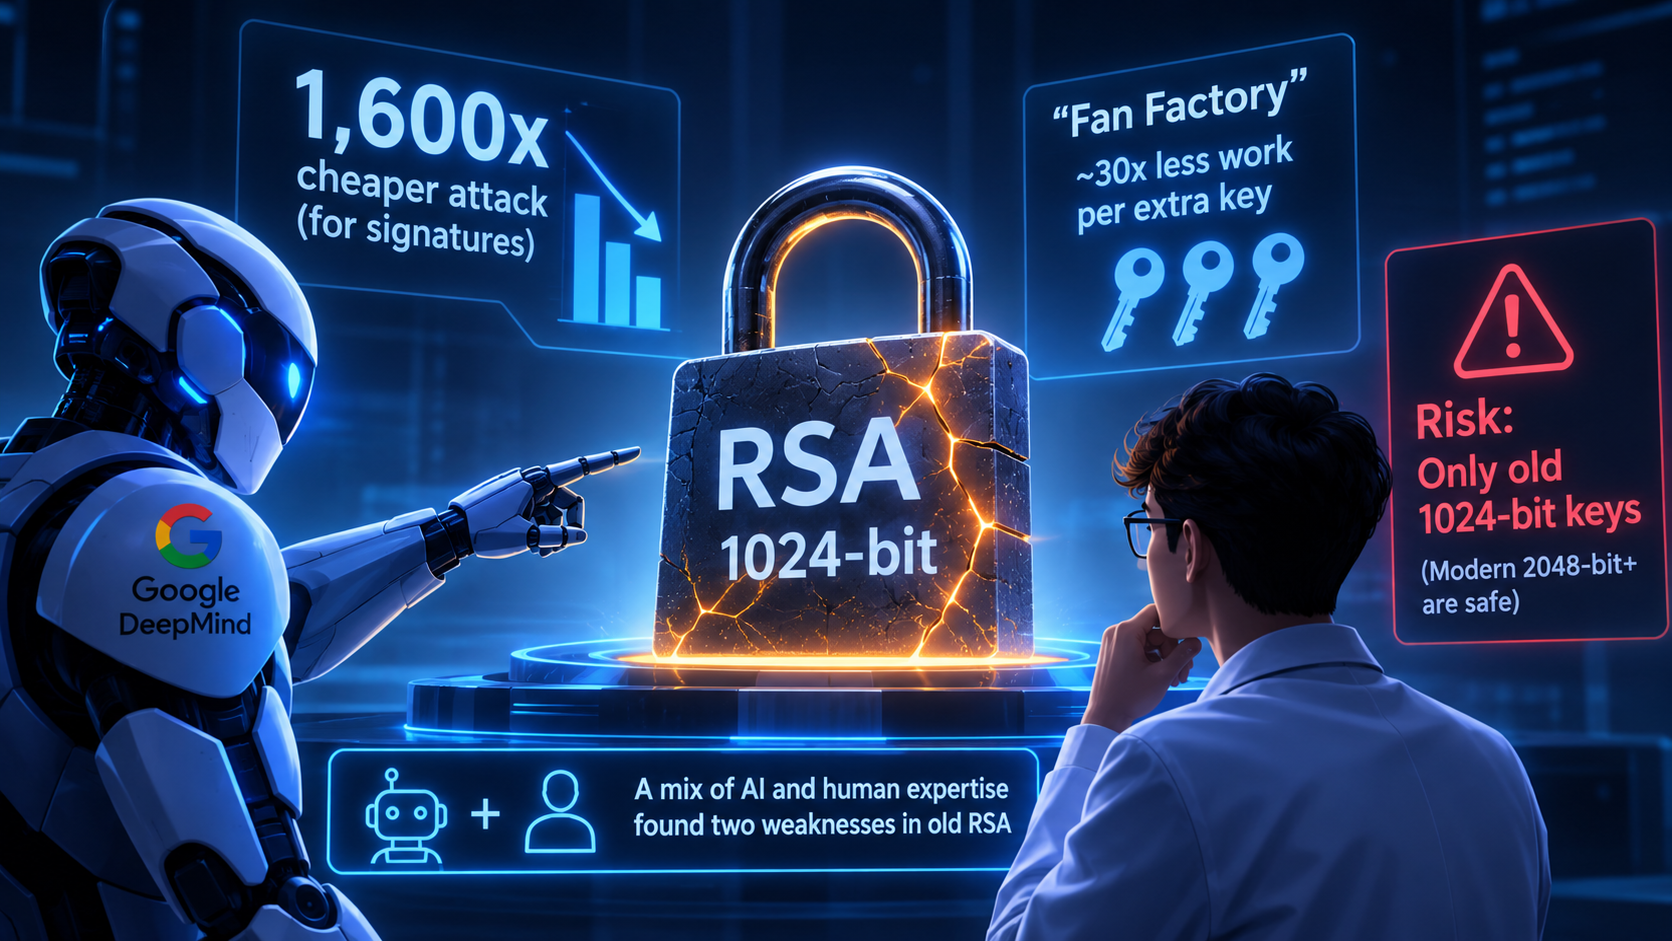
Google DeepMind’s AI agents cryptography research found two weaknesses in legacy 1024-bit RSA. Separating the theoretical speedups from the tested results is key to understanding the threat.
The DOJ has launched a Super Intelligence Task Force to centralize AI prosecutions. While it targets criminals, its push for corporate internal controls leaves AI developers with major questions.
Visa's Agentic Commerce Benchmark reveals AI shopping agents failed 42.8% of test runs, highlighting key trust and safety hurdles for autonomous AI.
The new OpenAI cyber model found 948 Linux root bugs for $1279 each in a single run. The numbers look striking, but key questions remain unverified.