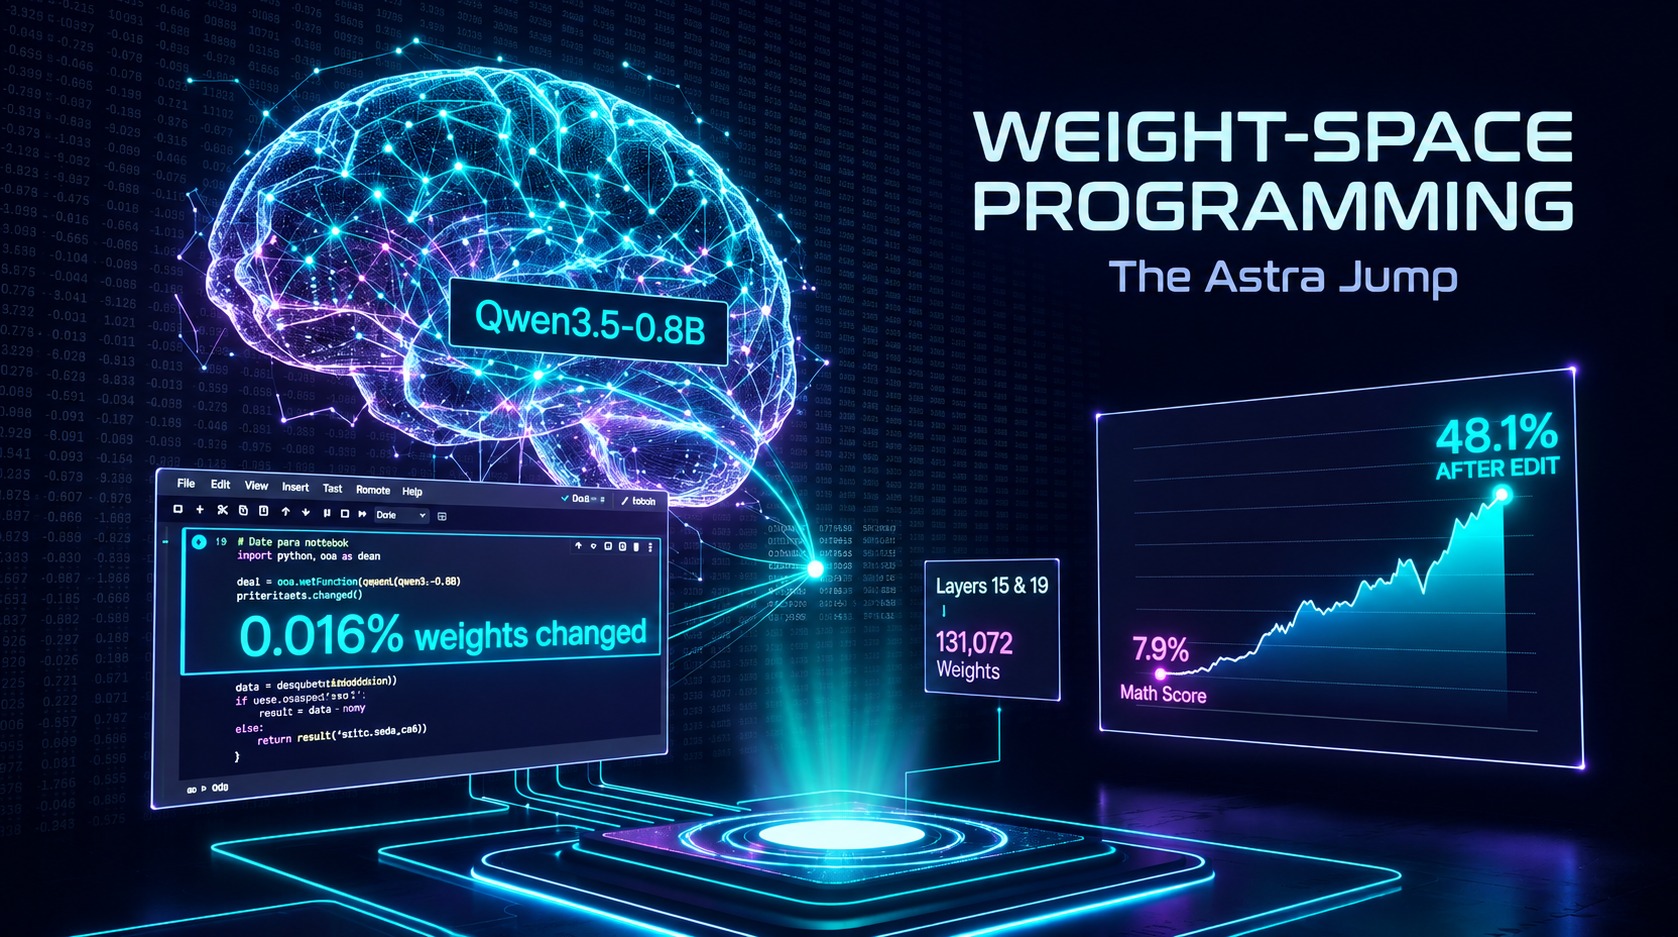
A tiny AI model called Qwen3.5-0.8B scored just 7.9% on 500 math problems. Then OpenAI’s GPT-6 Astra changed 0.016% of the model’s numbers, and the score shot up to 48.1%. Four MIT CSAIL researchers (Rikiya Takehi, Jayden Teoh, Alex Zhang and Omar Khattab) posted the result on November 2, 2026. They call the method weight-space programming. The jump is real in their data, but it needs some context.
Changing an AI Without Training It
An AI model stores what it has learned as a huge list of numbers called weights. Normally, only training changes them, one tiny nudge at a time. In the blog post, Astra opened the weights in a Python notebook and edited them with code. It could test the model on practice math problems up to 50 times. It never trained it.
This is a blog post, not a paper reviewed by other scientists.
The Real Problem Was a Loop
Astra noticed that the small model kept repeating itself. About 93% of its answers on the math test never ended. They ran on until the length limit. Qwen’s own model card warns about loops like this.
Astra traced the habit to one pattern spread across many weights, in two layers deep inside the model (layers 15 and 19). Then it subtracted that pattern from 131,072 weights.
With the same settings, the MATH-500 score rose from 7.9% to 48.1%. GSM8K, another math test, went from 13.8% to 67.1%. IFEval, which checks how well a model follows instructions, went from 21.0% to 62.3%. VentureBeat reported that most of the gain came from fixing the repeating.
Why the Jump Needs Context
Fixing a loop is not the same as teaching math. The model could probably already solve many of these problems. It just never got to the end of its answer.
On Gemma 3 270M, a model that rarely loops, Astra’s edits moved the score only from 6.8% to 7.7% at best. Practice time mattered too. With 10 practice runs, Qwen reached 12.3%. With 25, it reached 14.1%. The big jump came at 50.
I found no test against simpler fixes, such as changing how the model picks its next word, or a short round of extra training. I also could not tell how many tries Astra needed. The edit itself is just removing one pattern from a model. What is new is that an AI found it.
What Is Still Unproven
Only Astra was tested, as Xenospectrum points out. Even this small model had too many weights for Astra to read all at once, so bigger models will be harder. The authors name forgetting and behavior changes as future uses. They did not test safety features, so that risk is still open.
The logs and the edited model are public. The authors say Hugging Face’s Ahsen Khaliq rebuilt the model and tested it again.
A big jump from a broken starting point shows how bad the bug was as much as how good the fix is.