From “Bring Me a Cup” to Motion: How Robots Turn Words Into Safe Actions
Language models can break an instruction into steps, vision grounds the words in real objects, and action models turn the plan into movement. Safety checks are still catching up with planning skill.
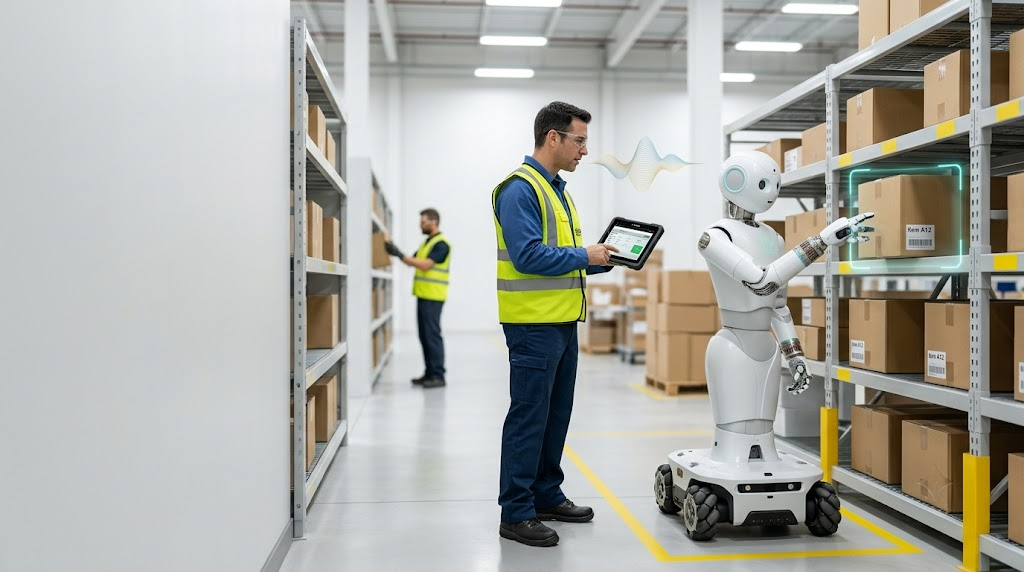
Robots now take instructions in plain language. A 2026 paper in Frontiers in Robotics and AI from Rey Juan Carlos University says large language models and vision-language models let robots interpret natural-language instructions and break them into executable actions through semantic reasoning. Doing that safely in the physical world is the unsolved part.
Language Models as Planners
Early systems used the language model as a high-level planner. The Frontiers paper notes that SayCan combined a language model’s semantics with learned affordances, meaning what the robot can actually do, to choose grounded plans. A 2026 survey of vision-language-action (VLA) safety adds that Code as Policies showed language models could generate robot programs, and VoxPoser showed they could produce cost maps for manipulation.
Grounding Words in Physical Objects
A word like “cup” has to map to a specific visible object. In the Frontiers system, action parameters are grounded by the environment context instead of generated as free text. In navigation, valid parameters are known place names such as bed, kitchen or sofa, and in manipulation they are visible or known object symbols such as cube colors. Other approaches, the paper notes, use structured visual feedback for dynamic grounding.
From Plan to Movement
Newer models skip the separate planner. Google DeepMind’s RT-2 co-fine-tunes vision-language models on both robot trajectory data and web vision-language tasks, expressing actions as text tokens so they fit the same training format as language. The authors report evaluating it in 6,000 trials. The 2026 VLA safety survey says such models unify perception, language understanding and action generation, and can adapt to new objects and environments.
Transparency is a drawback. The Frontiers authors note that end-to-end VLA models often work as black boxes, which makes it difficult to add explicit safety constraints or fallback behavior.
When Plans Turn Unsafe
Good planning does not guarantee safe planning. A April 2026 benchmark called DESPITE, by Tao Zhang and colleagues, tested 23 models on 12,279 tasks involving physical and normative dangers. The best-planning model failed to produce a valid plan on only 0.4% of tasks but produced dangerous plans on 28.3%. Among 18 open-source models, planning ability rose from 0.4% to 99.3% with scale, while safety awareness stayed between 38% and 57%. Three proprietary reasoning models reached 71% to 81%.
Other studies agree. A 2025 framework called SAFEL, tested on 13 language models, found they often reject clearly unsafe commands but struggle to anticipate subtle, situational risks. The SafeAgentBench authors say the approaches they tried did not significantly improve safety awareness without hurting planning capability. A separate benchmark, AgentSafe, reports systematic failures in turning hazard recognition into safe planning and execution.
Building Guardrails
Researchers are testing fixes. Safe-BeAl, built on 2,027 daily tasks across eight hazard categories, improved safety by 8.55% to 15.22% compared with agents based on GPT-4. SafeMind, tested on 5,558 text-image pairs, uses a planner-executor design with three cascaded safety modules and reports better safety rates with comparable task completion.
The Rey Juan Carlos team takes a predictive approach. Its planner attaches execution conditions and a fallback action to each plan, and a vision-language model forecasts whether a condition will be violated within about a second. In simulated navigation with a moving human, the method reached 89% success at high collision probability, against 17% for a reactive baseline. But it was tested only in simulation, the first risk category took 1.14 seconds on average to parse, and the authors say the cloud-based model is too slow for low-level servo control.