What Flint Is
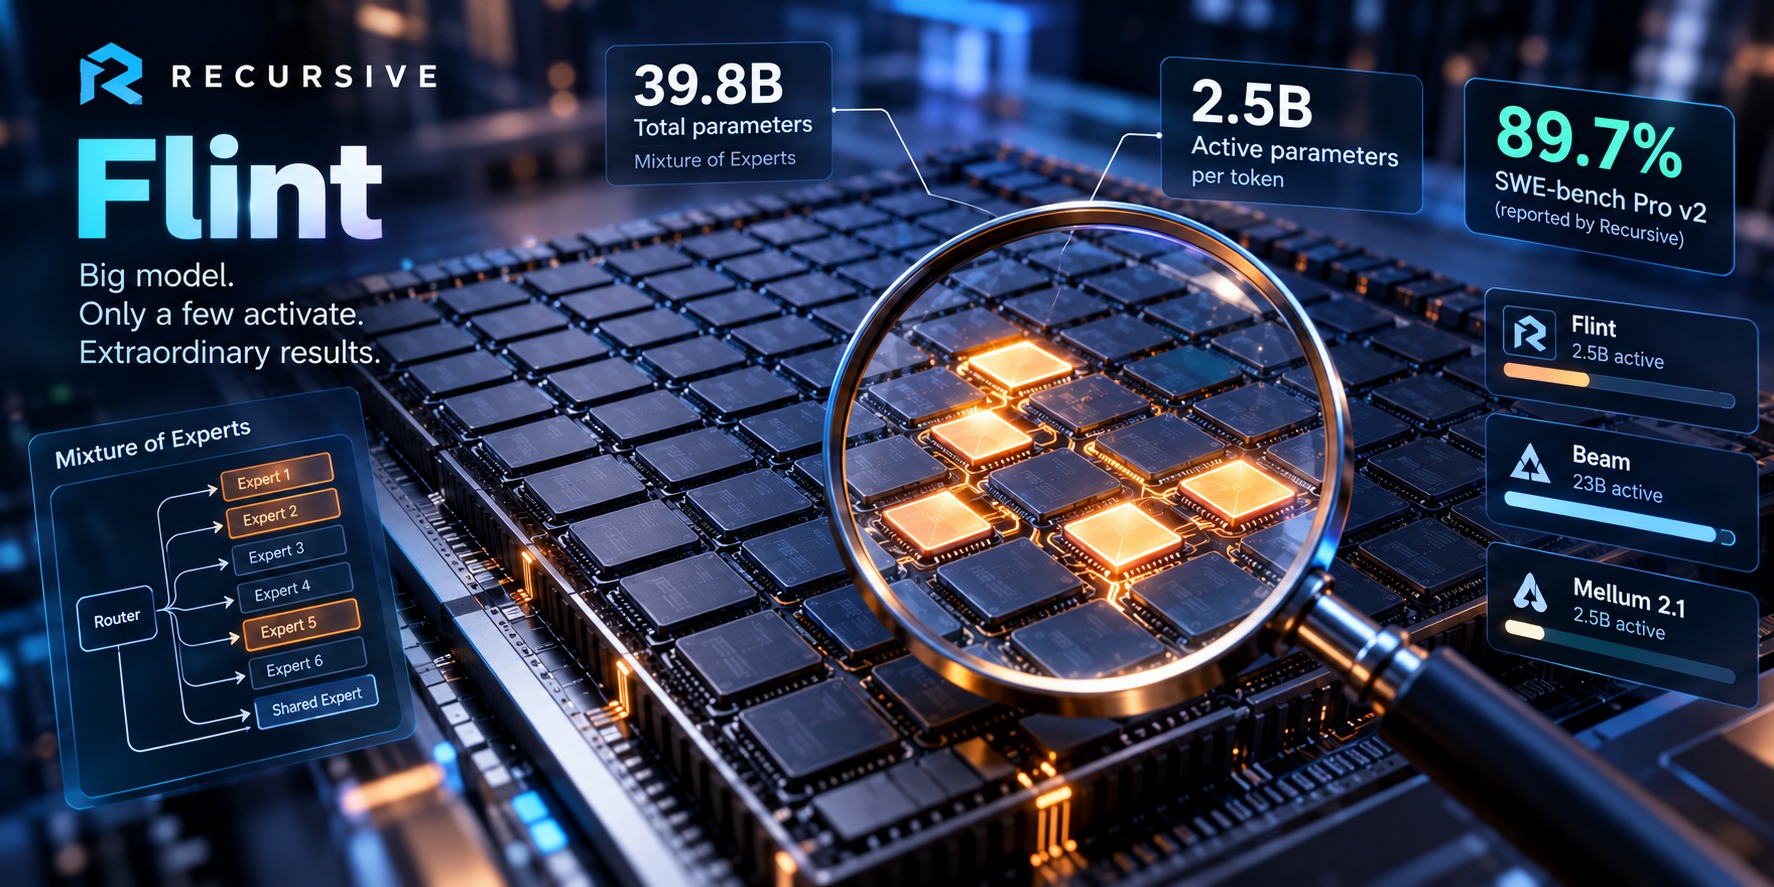
On October 21, a young lab called Recursive Superintelligence released Flint, an open coding model. It has 39.8 billion parameters, but only about 2.5 billion are active for each token. Recursive says it scores 89.7% on SWE-bench Pro v2. The weights are public, so anyone can test it. This article separates what Recursive claims from what has been checked.
Flint is a mixture-of-experts model. Think of it as a big team of specialists. Each expert layer has 256 of them. For every token, a router picks six, plus one shared expert that always runs. A token is a small chunk of text, about a word. That is why a 39.8 billion parameter model can run with the speed of a 2.5 billion one.
This is a working release, not a demo. The weights are on Hugging Face under the Apache 2.0 license, which allows commercial use. The context window is 262,144 tokens, which is how much text it can read at once. Recursive's 4-bit version takes about 23 GB and needs a Mac or GPU with 48 GB of memory. So "runs on a laptop" means a high-end laptop.
The Scores: Verified or Not
Recursive reports 89.7% on SWE-bench Pro v2, 74.2% on SWE-bench Verified and 54.9% on Terminal-Bench 2.1. All three are company-run results. No independent leaderboard has listed Flint yet.
The 89.7% needs the most care. Recursive measured the Pro v2 scores itself, and MarkTechPost notes they cannot be compared with the public SWE-Bench Pro. On that public version, Qwen3.6 scores 49.5%. So 89.7% does not mean Flint solves nine in ten real tasks. Recursive's own chart also shows the larger Qwen 3.8 scoring 94.9% on Pro v2 and 73.0% on Terminal-Bench 2.1. The real claim is narrower: Flint is the best mixture-of-experts model under 50 billion parameters on these tests.
Hands-on checks are thin. WIRED's Will Knight tried Flint and got it to build a small website. OpenHands tested it before launch but has not checked the benchmark claims. Recursive itself says Flint may need more guidance than large closed coding models.
The Eureka Machine Claim
The odd part is how Flint was built. Recursive says its Eureka Machine, an automated research system, helped develop nearly every part of the process. The system proposes ideas, builds them, tests them and picks what to try next. A small team of people and agents finished Flint in under four months.
Recursive gives three examples. The system searched expert layouts, starting from a 35B-total, 3B-active design, and landed on 40B and 2.5B. It found a way to shrink the output layer to 4 bits, and the smaller model scores within 0.7 points of the full one. It also wrote custom code to run Flint fast on Apple chips.
This is the company's own account, and no one has audited how much the machine did. It also does not prove self-improvement. The Decoder points out that Recursive would need to show that a model built this way makes the Eureka Machine a better researcher. CEO Richard Socher calls that the goal, not something Flint has shown.
Flint, Beam and Mellum 2.1
Two other open coding models landed this month.
Reflection AI's Beam was announced on October 5, and its weights are now on Hugging Face under Apache 2.0. It has 501 billion parameters, with 23 billion active. That is about nine times Flint's active size. Reflection says Kimi K3 still leads on raw capability, so Beam's pitch is efficiency, not the top score.
JetBrains' Mellum 2.1, released October 8, is the closer match. It has 12 billion total parameters and also about 2.5 billion active, under Apache 2.0. JetBrains reports 47% on SWE-bench Verified, against Flint's 74.2%. But JetBrains built it as a fast helper inside larger agent systems, not as a main coding model. Both numbers are self-reported with different setups, so the gap is a hint, not a ranking.
Why It Matters
If the numbers hold, active parameters are not the whole story. Better design, compression and fast code can matter as much as raw size. That would make private, offline coding help possible on one machine, with no API fees and no code sent to a server.
Two things are still unproven. One is whether Flint holds up on messy, real projects. The other is whether automated research can keep improving models without people steering it. Treat both as open questions.
What to Watch
Look for independent runs of SWE-bench and Terminal-Bench on the open weights, reports from developers using Flint on real projects, and more detail on how the Eureka Machine works. Anyone can download Flint and run the tests. If the results match, the claim stands. If they do not, the gap will be the story.


