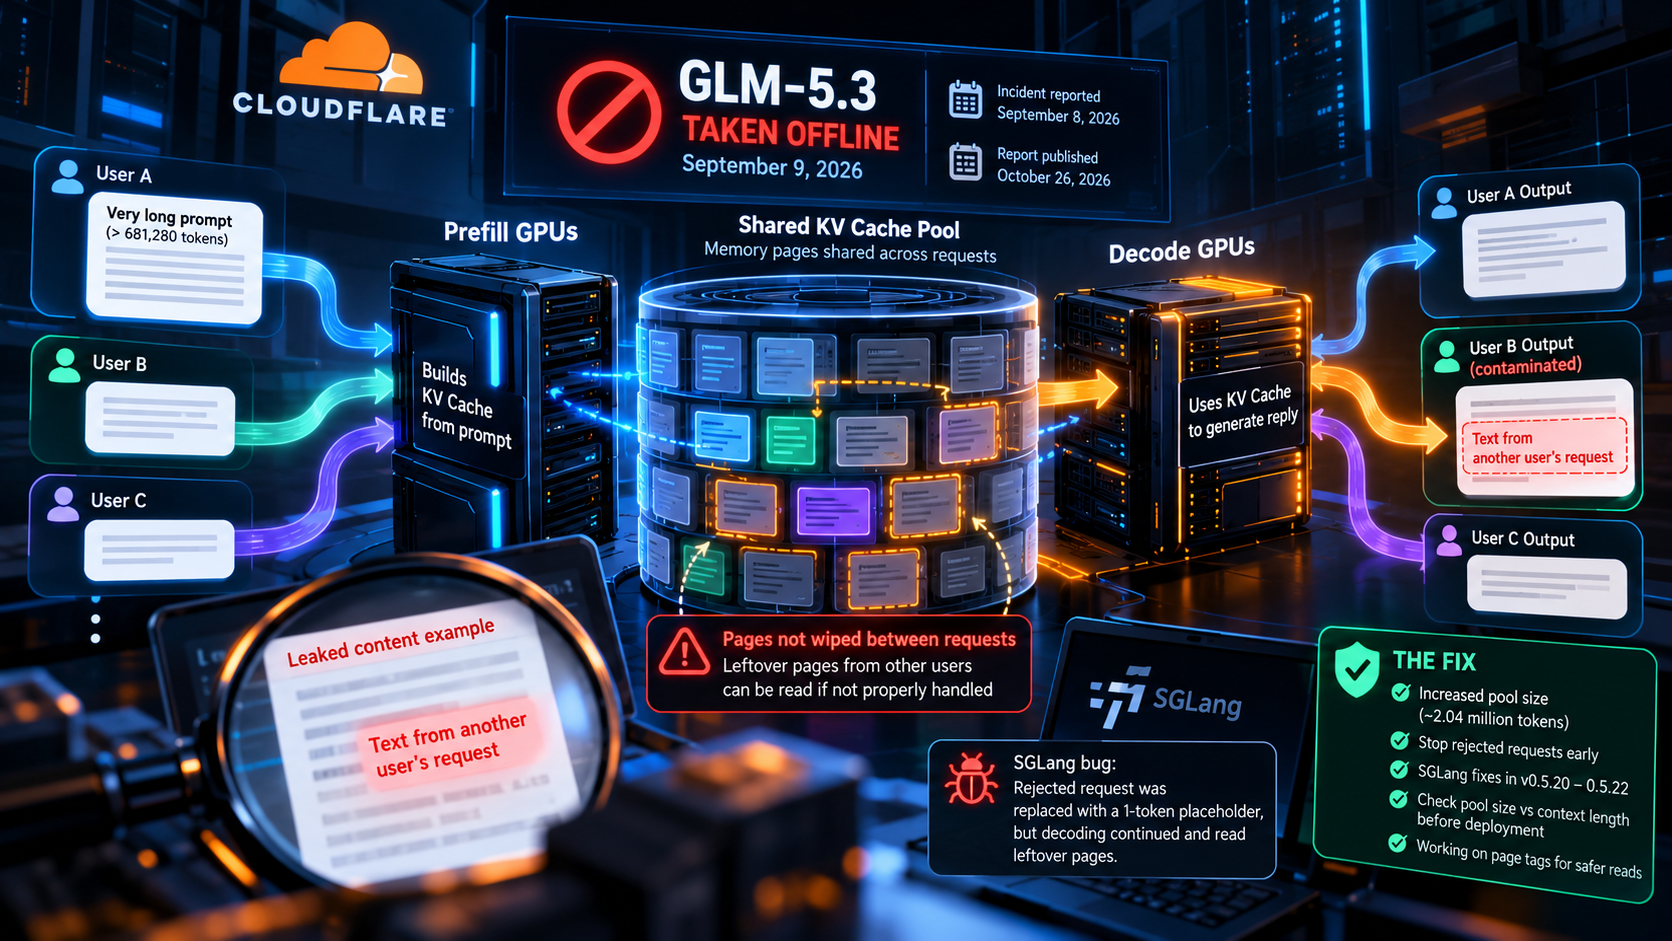
Cloudflare says 155 responses from GLM-5.3 on Workers AI contained other customers’ data between August 27 and September 9, 2026. Its October 26 post explains how. A separate write-up from the researcher’s firm, Knostic, shows what the leak looked like from outside. Together they point to a plain lesson: AI systems keep state, and that state needs the same walls as a database.
How the model is served
When you send a prompt, the model builds a KV cache, which is like notes about every token. Cloudflare splits the work. Prefill GPUs read the prompt and build the cache. Decode GPUs use it to write the reply. The cache sits in a shared pool of memory pages that are not wiped between requests. The inference engine, SGLang, tracks who owns each page. It sizes the pool itself at startup. The model’s context length is a separate setting, and nothing forces the two to match.
What went wrong
Cloudflare’s post names two overlapping causes. First, it launched GLM-5.3 with a 1,048,576-token context window, but the prefill pool held only 681,280 tokens. Cloudflare says it knew this before launch and expected the engine to reject oversized prompts. Its long-context tests returned success codes, so it moved on.
Second, an SGLang bug. A prompt too big for the pool was swapped for a one-token placeholder, but the request wasn’t stopped. Decode was told the transfer was complete and read leftover pages from earlier users.
What an outside test found
According to Knostic’s report, its CEO, Gadi Evron, noticed odd output while working through OpenRouter, traced it to Cloudflare on September 7, and reported it on September 8. In black-box tests, Knostic sent prompts of growing size with a unique marker inside. The marker came back at 662,162 tokens and vanished at 700,168. Knostic treats that as an estimated boundary, not a root cause. The leaks it saw included names, invoice numbers, euro amounts, file paths and agent task records. One matched a public project created after the model’s training cutoff, so it wasn’t memorized text. An ordinary paid account was enough. Tests on three sibling models found no leak, which backs Cloudflare’s claim that no other model was affected.
The fix, and its limits
The “Immediate remediation” section of Cloudflare’s post says the prefill pool now holds about 2.04 million tokens, so any valid prompt fits. The engine was also patched to stop rejected requests early. Cloudflare restored the model on September 9. Knostic says its report was marked resolved on September 24, and public disclosure came October 26. Cloudflare’s post doesn’t say how many customers were told.
Not the first time
In March 2023, OpenAI’s own postmortem traced a ChatGPT leak to a bug in an open-source library, redis-py. It let some users see other users’ chat titles. OpenAI also said payment details of 1.2% of active ChatGPT Plus subscribers in a nine-hour window may have been visible, and, as Help Net Security reported, it emailed those users. The layer was different. The pattern was the same: shared state, an edge case in a dependency, and a check that missed it. This time the shared state sits below the model.
Why it matters, and what could come next
Cloudflare admits it tested response codes and speed, not whether output made sense. A system can answer fast and answer wrong. Two settings also had to match, and nothing enforced it. Cloudflare now checks pool size against context length before each deployment. Its “Integrity by construction” section describes page tags that catch wrong reads, at under 1% cost in its own tests. It switched them off on GLM-5.2 over reliability issues, so that is still a prototype. Operators of disaggregated SGLang should upgrade to 0.5.22 or later.


