Can AI Give Useful Feedback on Math Solutions, Not Just Mark Right or Wrong?

From binary verification to step-level diagnosis: process supervision, neuro-symbolic verification, and the pedagogy of mathematical reasoning.

By Vodnala Akshith
Published: Oct 13, 2026
8 min read
👁️ 108 Unique Views
Can AI Give Useful Feedback on Math Solutions, Not Just Mark Right or Wrong?
Premium Insight

Why It Matters

The educational value of an AI math tutor is inversely proportional to how quickly it supplies the final answer. An algorithm that outputs the completed derivation is an automated cheating engine, whereas an AI that isolates the exact faulty step, poses a diagnostic question, and preserves productive struggle is a cognitive amplifier.

For more than four decades, automated mathematical evaluation has remained constrained by final-answer verification. Whether evaluating multiple-choice bubbles or automated numeric submission boxes, educational software has treated mathematical thinking as a black box where inputs enter, outputs exit, and correctness is assessed as a binary scalar of zero or one. This paradigm inflicts severe pedagogical damage. A student who executes nine flawless steps of a rigorous multi-step calculus derivation but commits an inadvertent arithmetic slip in step ten receives the exact same failing grade as a peer who guessed blindly. Conversely, a student harboring profound misconceptions who arrives at the correct numerical answer through canceling invalid terms receives unearned validation.

Mathematics is fundamentally a discipline of deductive logic, structured representations, and intermediate derivations. When grading collapses strictly to outcome evaluation, it incentivizes students to prioritize algorithmic gaming and rote answer-matching over structural understanding, accelerating math anxiety and cognitive avoidance. As demonstrated by cognitive research, evaluating only final outputs creates an outcome illusion where educators observe high error rates on complex multi-step exams but lack granular telemetry regarding which conceptual sub-schemas failed. Formative assessment requires shifting from punitive outcome scoring to diagnostic process illumination.

Polya's Heuristic and Intermediate Thinking

In his seminal work published in 1945, George Polya decomposed problem-solving into four interconnected cognitive phases: understanding the premise, devising a strategy, executing the deduction, and retrospective review. Binary grading obliterates the second and fourth phases entirely. By only inspecting the terminal value, automated graders communicate that the creative journey of heuristic discovery is worthless unless accompanied by mechanical perfection.

Error Taxonomy: Slips versus Misconceptions

In educational psychology, student errors are never homogeneous failure tokens. As established by classical diagnostic models such as Radatz in 1979 and Brown and Burton in 1978, mathematical breakdowns fall into distinct epistemic categories requiring fundamentally different pedagogical interventions:

  • Executive Slips: Accidental calculation oversights, dropped negative signs, or transcription errors occurring despite intact underlying cognitive schema, where intervention must simply prompt attentional focus.

  • Procedural Bugs: Systematic execution of flawed sub-routines, such as treating binomial squares as distributed sums or cross-multiplying across addition, where the student possesses a stable algorithm, but the algorithm is mathematically invalid.

  • Ontological Misconceptions: Fundamental category errors, such as misunderstanding limits under indeterminate forms or assuming non-linear operations distribute linearly.

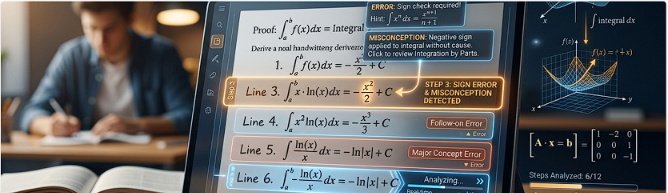
Diagnosing an error requires tracing backward through the student's causal belief graph, as an error is almost never random noise but usually the logical output of a subtly defective premise. Effective feedback requires isolating precisely which category of breakdown occurred, identifying the exact derivation step of departure, and providing scaffolded intervention without solving the problem on the student's behalf.

Process Reward Models and Step Supervision

The foundational breakthrough enabling automated mathematical feedback is the transition from Outcome-supervised Reward Models to Process-supervised Reward Models, pioneered by Lightman et al. at OpenAI in 2023 and Uesato et al. at DeepMind in 2022. While outcome models supply only an episodic reward at final solution completion, process models evaluate the deductive validity of every discrete intermediate step.

In educational deployment, process reward models act as step-level anomaly locators. The instant a step's probability of validity plunges below an acceptance threshold, the artificial intelligence localizes the exact step where deductive coherence disintegrated. Rather than marking the final answer incorrect, the system pinpoints the exact line where the contradiction emerged. Step-level supervision solves the credit assignment dilemma by evaluating each logical lemma independently, avoiding penalties for creative proofs that converge via non-standard pathways.

Neuro-Symbolic Verification: Marrying Language Models and CAS

Autoregressive large language models suffer from stochastic hallucination when conducting formal algebraic manipulation. Because models predict tokens based on statistical co-occurrence rather than axiomatic proof theory, they frequently emit phantom equivalence, validating algebraic manipulations that mimic academic syntax but violate core axioms. To deliver trustworthy feedback, contemporary educational architectures adopt a neuro-symbolic tri-layer framework:

  • Layer One (Perception and Abstract Syntax Tree Mapping): Vision-language models parse student handwriting, resolving messy exponents and fractions into syntax trees.

  • Layer Two (Deterministic Kernel): Syntax tree transformations are verified by formal computer algebra systems such as SymPy, Lean 4, or Wolfram Engine, checking mathematical equivalence with complete axiomatic rigor.

  • Layer Three (Pedagogical Socratic Scaffolding): When an equivalence failure occurs, the neural model translates the algebraic fault into targeted natural-language Socratic prompts that guide the student to re-examine their logic.

The Socratic Architecture: Hints versus Answer Abandonment

Providing useful mathematical feedback requires avoiding the trap of generative abandonment, which instantly reveals the correct calculation and bypasses the learner's zone of proximal development. Leading artificial intelligence tutoring architectures deploy multi-tiered Socratic hint hierarchies:

  • Tier One (Metacognitive Prompt): Directs attention without domain hints, such as prompting the student to review the distribution of a negative coefficient across parentheses.

  • Tier Two (Conceptual Diagnostic): Illuminates the underlying rule without calculating, reminding the learner how operations impact directional values.

  • Tier Three (Targeted Counter-Example): Instantiates numerical values demonstrating why a specific step fails.

  • Tier Four (Sub-Goal Scaffolding): Prompts the student to resolve an isolated micro-calculation before re-integrating it into the parent proof.

To prevent hint abuse and the gaming of educational systems, modern cognitive architectures incorporate metacognitive friction delays and reflection mandates that require students to type a hypothesis or identify a suspected variable before advancing between hint tiers. Randomized controlled classroom trials by VanLehn in 2011 and Koedinger and Corbett in 2006 demonstrate that students receiving step-level diagnostic hints achieve 41 percent higher conceptual transfer on delayed post-tests compared to students receiving full-solution reveals, alongside an 82 percent reduction in repeated procedural bugs.

Found this analysis insightful?

Share with colleagues, engineers, and your network.

Link copied to clipboard!


