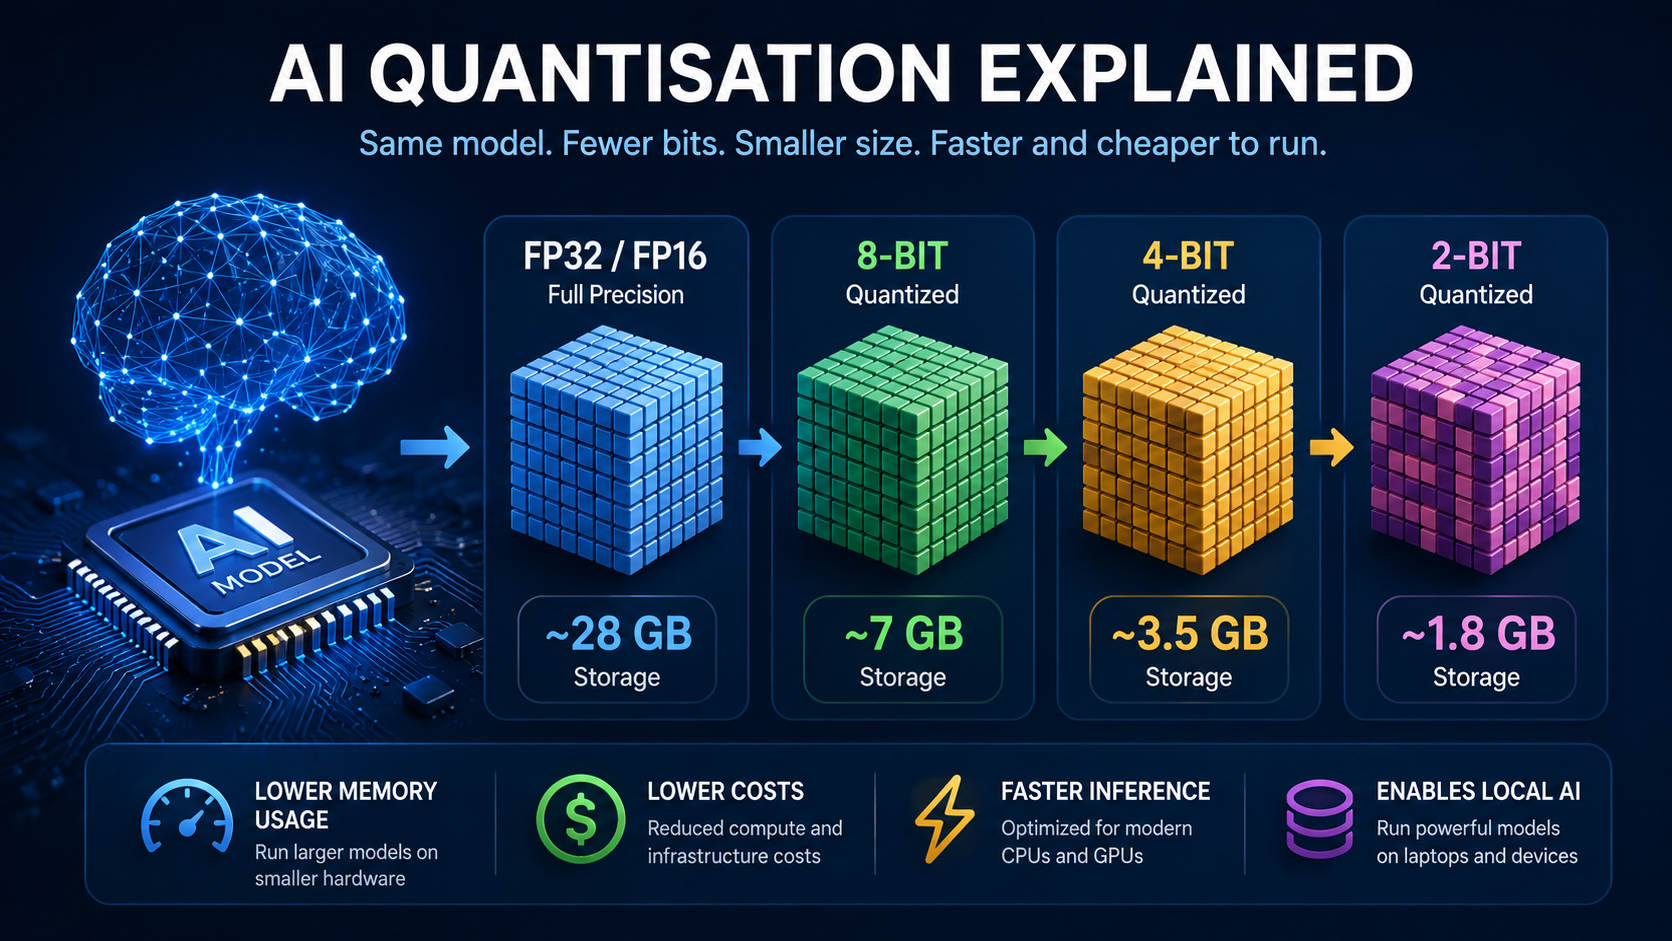
How to Put a Large AI Model on a Diet Without Removing Its Brain
What does 4-bit or 8-bit AI actually mean? Learn how LLM quantisation shrinks models, reduces memory use and helps run AI locally.
Tracking the latest breakthroughs, research, and deep-tech innovations.
What does 4-bit or 8-bit AI actually mean? Learn how LLM quantisation shrinks models, reduces memory use and helps run AI locally.
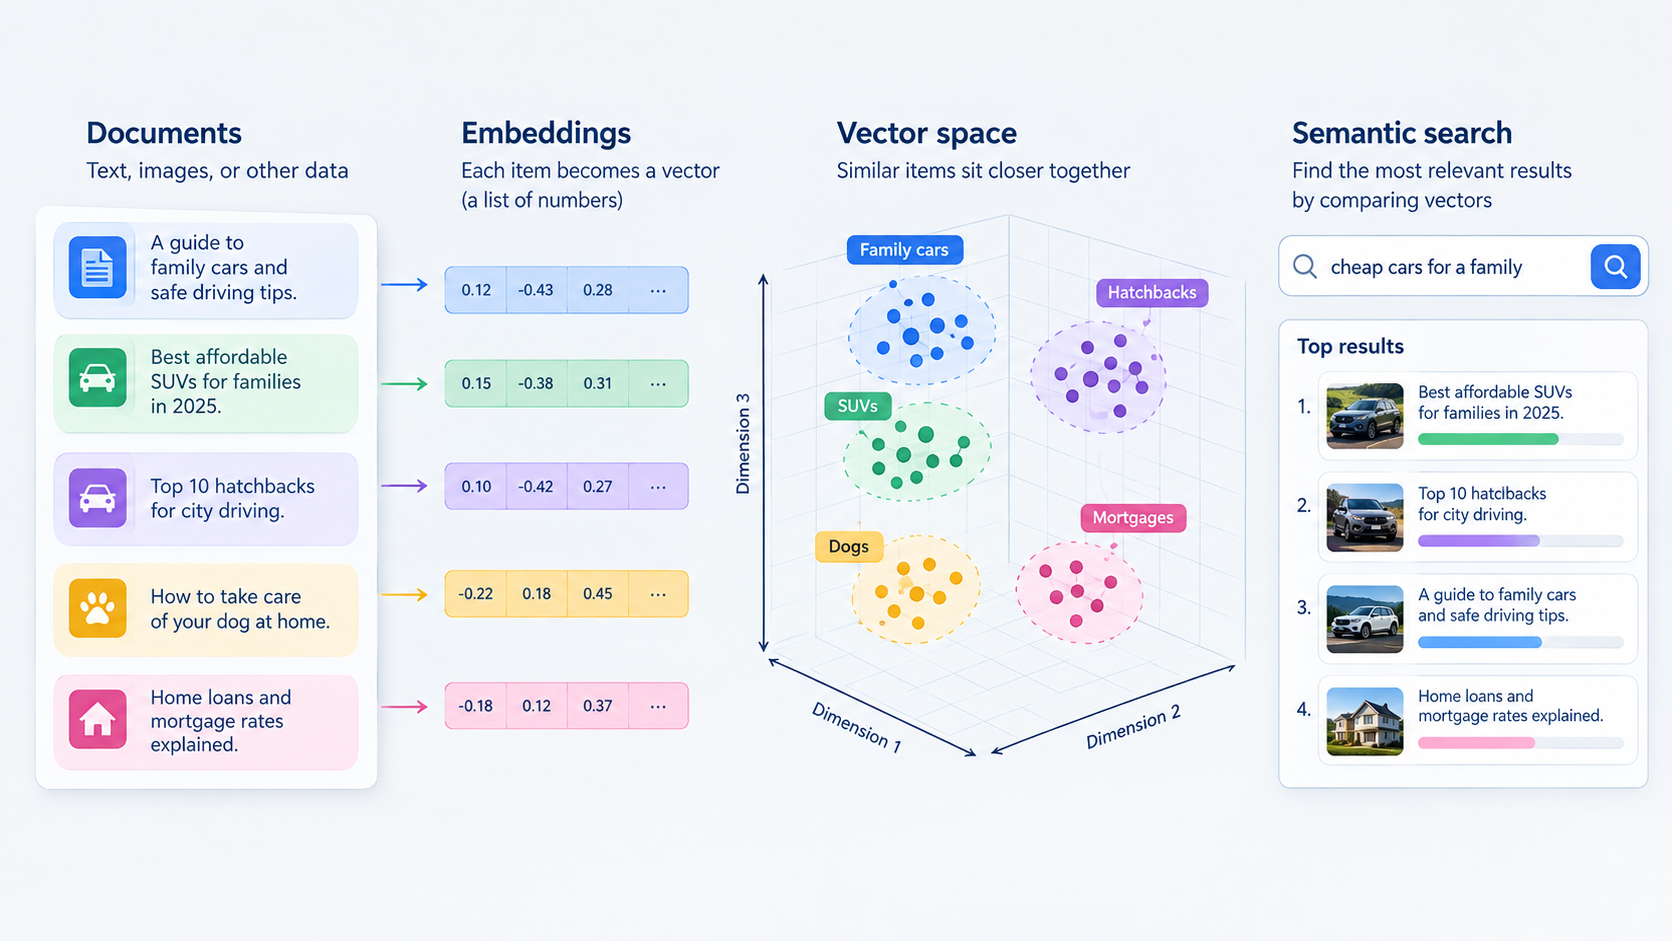
Learn how AI embeddings turn words, documents and images into vectors, powering semantic search, recommendations, RAG and modern AI applications.
What does a 1-million-token AI context window actually mean? Learn how tokens are counted, how AI companies charge for them, why context length matters and why bigger is not always better.
MeitY has officially booted India's next-generation sovereign AI compute cluster, AIRAWAT-2, deploying over 10,000 localized enterprise GPUs in Navi Mumbai to power local LLM training and strategic research infrastructure.
An inside look at how NVIDIA, Groq, and Apple are verticalizing their compute stacks to dominate the inference economy.
New research proposes low-rank adaptation techniques tailored specifically for low-resource Indic language tokenizers, reducing computational overhead by 40%.