Five small AI models working as a team solved ten hard coding problems 49 times out of 50 tries. Claude Fable 5, a top model from Anthropic, solved 8 of the 10 in a single try. That is the headline from Memdoor, a free tool whose author rebuilt a method called GVS5H from a 2026 research paper. Each small model is Qwen3.8-27B, an open model with 27 billion parameters, the adjustable numbers that hold what an AI has learned. The result is real, but it is smaller than it sounds.
How the Team Works
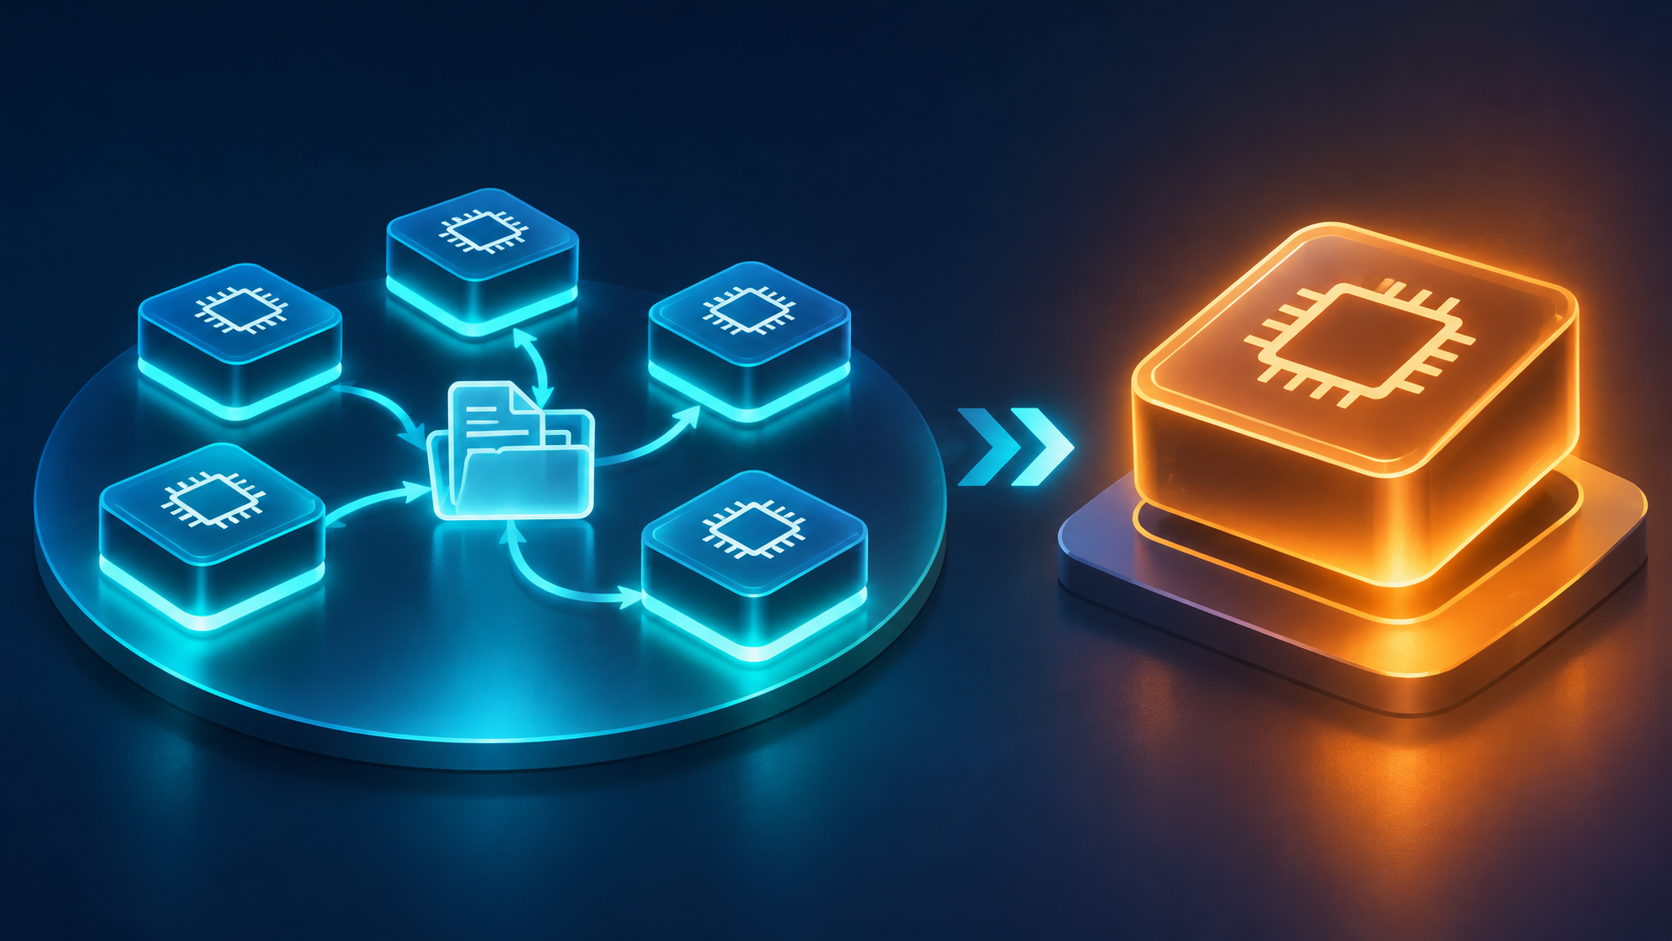
The team has a planner, two idea-generators called ideators, a solver, a manager and a repair worker. They never chat with each other. Each one starts fresh and communicates only by reading and writing files on disk, such as a plan file and a solution file. It works much like coworkers who leave notes on a shared desk. The workflow reuses the paper’s own prompts, so it tests the method rather than clever new wording.
What the Numbers Show
Memdoor’s author ran the first ten problems from LiveCodeBench Hard, a set of tough coding-contest questions, five times each. The team averaged 9.8 problems solved out of 10, against 9.6 for the original authors’ harness. The 50 runs cost $35.79, and a typical run took about forty minutes.
Fable’s 8.0 comes from one try per problem, taken from the paper’s files, and it was not run inside this harness. So it got no notes, no retries and no repair step, which means the two sides did not get the same help.
Why Ten Problems Is Thin
With ten problems, a single problem moves the score by ten points. The paper tested 100 problems, and its first version reported 92.4% for the Qwen team against 90.4% for Fable 5. A later revision reports 86.4% against 87.4%, so Fable was a point ahead, and the authors’ own statistics show no clear difference. The same Fable scored 8 of 10 here, so this set of ten may simply be harder or unlucky.
The problems also come from contests held in March and April 2025, and the README admits the model may have seen them in training. Whether the shared files leak partial answers between agents is a fair question I could not settle, and I do not know if the repair worker saw failing tests.
What It Does Prove
The cost story needs care too. The paper prices a 100-problem run at $51.75 for the Qwen team and $61.11 for Fable 5, a saving of about 15%, not the 9% first advertised for a different model. Memdoor’s runs averaged about $0.72 each by my arithmetic, above the paper’s roughly $0.61 per Fable problem, though the price rates may differ.
What the experiment does show is that how you organize a model can matter as much as which model you pick. It does not show that small models beat big ones.