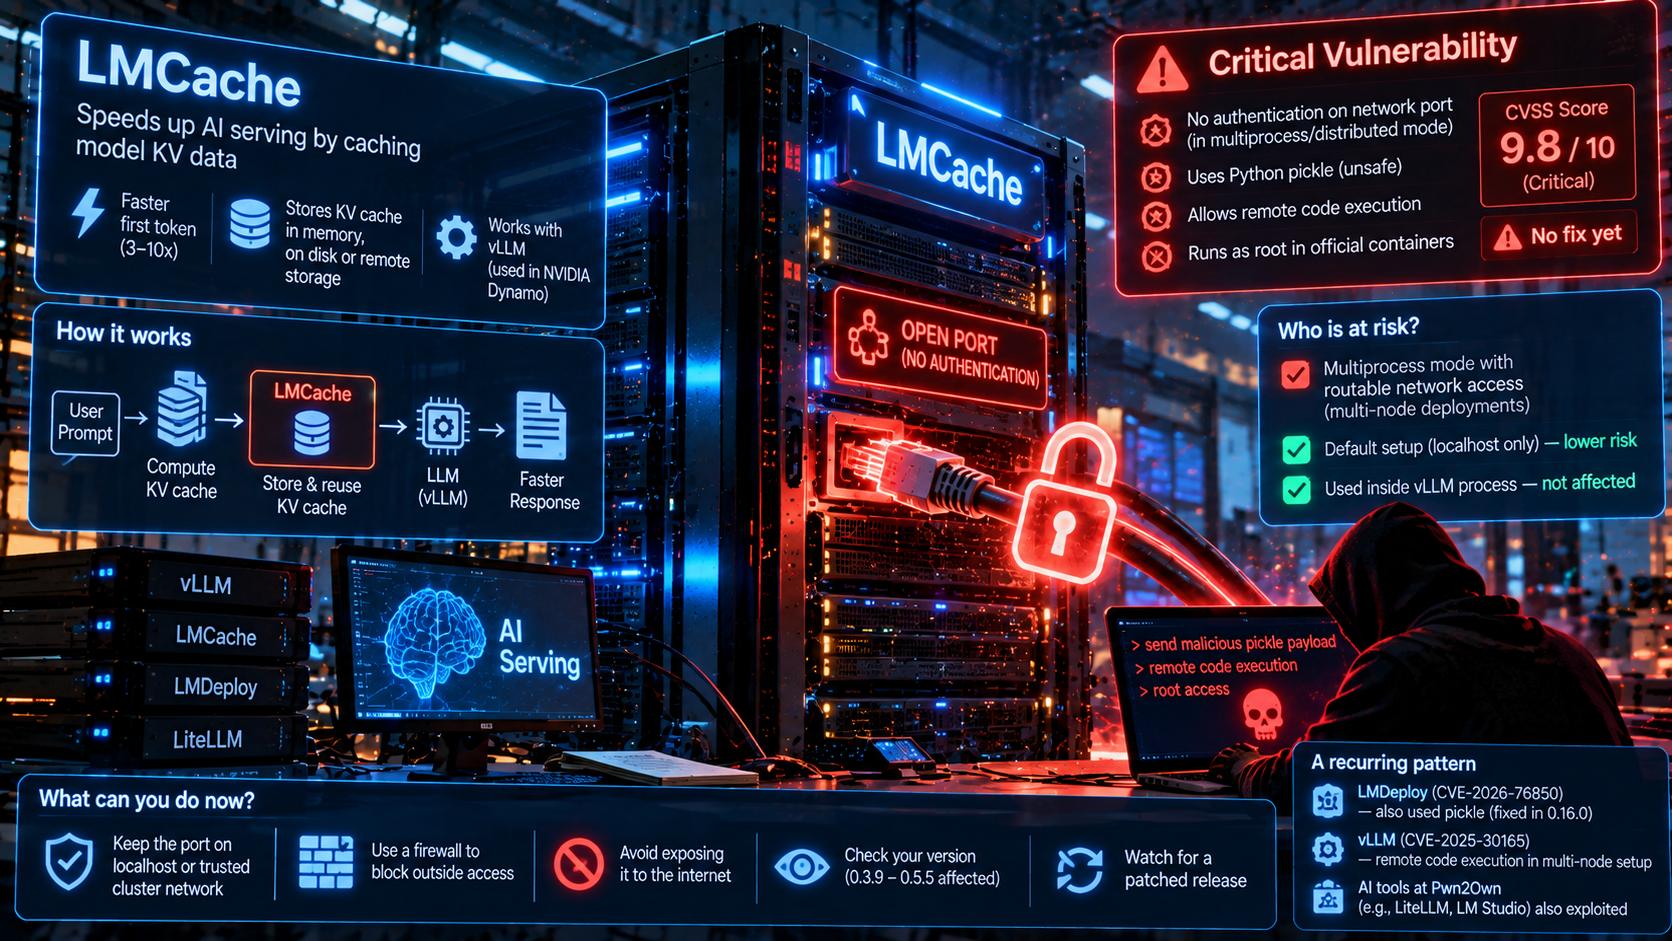
Most talk about AI security is about chatbots being tricked. This week's news is about plumbing. On October 7, researchers at JFrog published a critical flaw in LMCache, a tool that helps AI servers answer faster. As of that report, no fixed version exists. The flaw is serious, but it does not hit everyone. The details show who needs to act.
What LMCache Does and What Broke
When a language model reads a prompt, it computes working data for every token. This is called the KV cache, short for key-value cache. Recomputing it for repeated text wastes time and GPU power. LMCache stores these caches in CPU memory, on disk or in remote storage so servers can reuse them. Its developers say this can cut the wait for the first token by 3 to 10 times in some cases. That is their own claim. It works with vLLM and appears in NVIDIA's Dynamo documentation.
The flaw sits in LMCache's multiprocess mode, also called distributed mode. In that mode, LMCache opens a network port so worker processes can share cache data. JFrog says that port has no authentication, and one kind of message is decoded with Python's pickle. Pickle is a format for saving Python objects. Loading a pickle can run code hidden inside it, which is why it is unsafe to load from a source you do not trust.
The result, per JFrog, is that anyone who can reach the port can run code as the user running LMCache. In the official container images, that user is root, the most powerful account on the machine.
Who Is Actually at Risk
The headline score is 9.8 out of 10 on the CVSS severity scale, which counts as critical. But JFrog says the score applies to one setup: multiprocess mode bound to an address other machines can reach, which is how multi-node deployments work. By default, the port listens only on the local machine. LMCache used only inside a vLLM process does not open it at all.
Affected versions start at 0.3.9, which shipped on October 29, 2025. JFrog says the problem is still present in the latest release, 0.5.5, in the 0.5.6 release candidates and in the development branch as of October 7. No fixed version had been published. JFrog both found the flaw and assigned the CVE number, and the US government's vulnerability database had not yet analyzed the entry. None of the reports found here mention attacks in the wild.
For now, JFrog advises against setting a routable address. Keep the port on localhost or a trusted cluster network, and use a firewall. A firewall reduces who can connect, but it does not remove the flaw. Anyone who can still connect can run code.
A Pattern, Not a One-Off
The same mistake appears elsewhere. In August, the LMDeploy serving tool received CVE-2026-76850 for loading pickle data in its disaggregated serving feature. It was fixed in version 0.16.0 by switching to JSON. vLLM had an earlier remote code execution flaw in its ZeroMQ-based multi-node setup, tracked as CVE-2025-30165. At Pwn2Own Berlin in May, AI tools such as LiteLLM and LM Studio also fell, using chains that included server-side request forgery and code injection.
Pwn2Own Ireland adds context, with a caution. On day one, October 6, organizers paid $388,500 for 32 unique zero-days. A zero-day is a flaw its maker does not yet know about. The targets included phones, printers and smart-home devices as well as AI tools, so the 32 flaws were not all AI software. On the AI side, one researcher reportedly got a shell on LiteLLM, and another took down OpenAI Codex with a single argument-injection bug. Vendors get 90 days to fix these flaws before details go public, so little is known about them yet.
The common thread is trust. Serving tools are built for speed inside clusters that developers assume are private. A flaw like this shows what happens when that assumption fails.
What Operators Should Do and What Comes Next
In the near term, the checklist is short. Find out whether you run LMCache in multiprocess mode. Check which address its port listens on. Block outside access, and watch the project for a patched release.
The long-term question is whether AI serving tools will become safe by default, with authentication and safe data formats. That is a prediction, not a finding. Until a fix arrives, teams that do not need multi-node sharing are safest staying in single-host mode with default settings. More broadly, treat internal AI services as if someone could reach them.