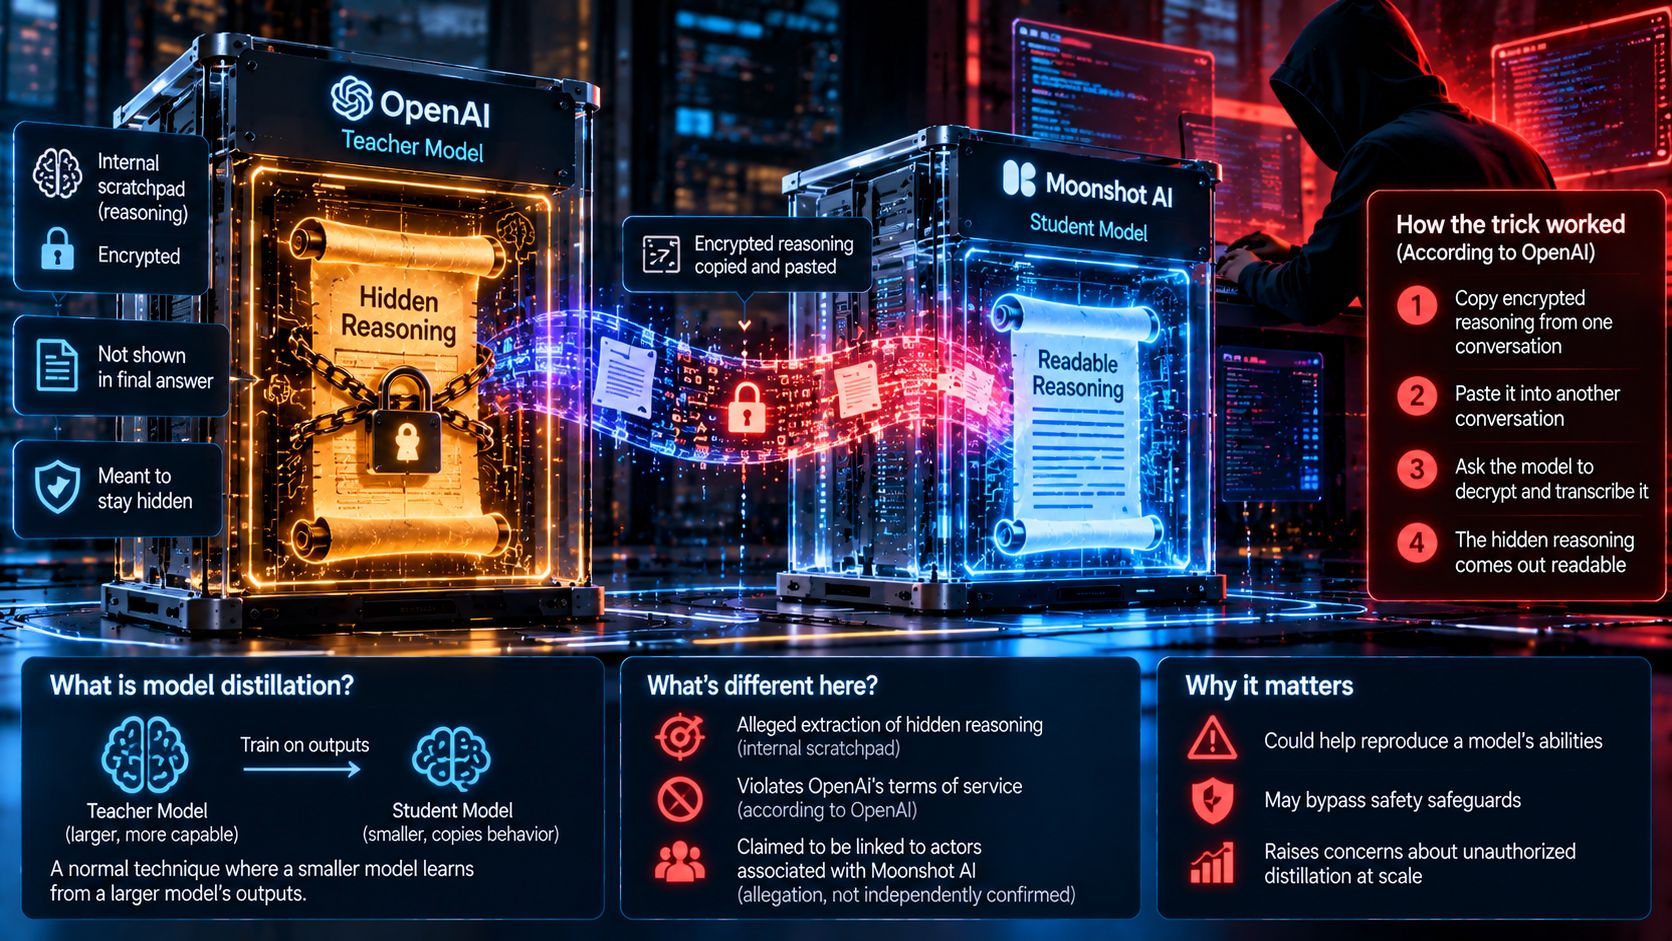
On September 30, 2026, OpenAI said it had disrupted a campaign to pull hidden reasoning out of its models. It says a "core cluster" of the activity came from people associated with Moonshot AI, the Chinese company behind the Kimi models. This is an allegation. I found no response from Moonshot to OpenAI's report.
The case matters because of how the reasoning was allegedly taken. OpenAI says nobody broke its encryption. The operators used the model itself to read what was meant to stay hidden.
What Model Distillation Is
Distillation means training one model on the answers of another. A smaller "student" model learns to copy a bigger "teacher." It is a normal technique, and companies use it on their own models all the time. OpenAI's policy lead, Caroline Zier, told Bloomberg the concern is a violation of its terms of service, not open models or legitimate distillation.
OpenAI calls what it saw "adversarial distillation." It defines this as the systematic, unauthorized use of one model's outputs or reasoning to help train, reproduce, or improve another model.
The target was reasoning. OpenAI's models work through a problem in an internal scratchpad before they answer. OpenAI keeps that scratchpad encrypted. It says extracting it can reveal information the final answer leaves out, and help others reproduce the model's abilities.
How the Trick Worked
Here is OpenAI's account. The operators copied encrypted reasoning from one conversation. They pasted it into another conversation and asked a model there to decrypt and transcribe it. The model obliged, and the hidden text came out readable.
The design makes this possible. Some APIs return an encrypted block of reasoning, and the developer sends it back so the model can pick up where it left off. That makes the block portable. OpenAI says the operators did not break the encryption, compromise a database, or reach stored user conversations. It closed a path that let someone replay another user's encrypted reasoning, and added checks that hold streamed output that might expose reasoning.
Outside researchers found a related weakness. An August 2026 arXiv paper showed that encrypted reasoning from a stronger model could be fed to a weaker model from the same provider to get plain text. Their tests covered OpenAI, Anthropic, and Google. OpenAI says it confirmed those attack paths were real and that the problem is not unique to its models.
What Is Claimed and What Is Not Known
These points come from OpenAI's own report. No independent party has checked them.
Activity began on July 1 at low volume. On July 24 and 25, OpenAI saw 16,000 requests using an extraction pattern from more than 4,000 users. It found related activity across more than 15,000 users and says it fully disrupted that cluster by July 28. A footnote says these figures count attempted extractions, not necessarily successful ones.
OpenAI also admits limits. It says it is unclear whether all operators were a single actor. It did not say how many of the users it ties to Moonshot. It has not shown that Moonshot used any extracted reasoning to train Kimi.
Moonshot has not answered this report, as far as I could find. It did deny a separate claim in July from a White House official that Kimi K3 was built by distilling Anthropic's Fable model. Anthropic has also accused Moonshot of distillation. Those are other cases with their own evidence. Experts disagree on how much distillation explains Kimi's quality. OpenAI's own Dean Ball said it plays a role but is clearly not the main factor.
Why It Matters and What Could Come Next
OpenAI argues the risk goes beyond business. Extracted reasoning could train a model without the safeguards on the original's answers. At scale, it says, distillation can move advanced abilities across without the same investment in safety. That is OpenAI's view. Some researchers argue that model outputs are not copyrighted and that US claims against Moonshot are political.
In the near term, expect tighter controls. OpenAI banned or restricted accounts, strengthened sign-up checks, and shared its findings through the Frontier Model Forum and government channels. It also says it expects attempts to become more sophisticated as models improve.
The long-term picture is speculation. Providers may stop returning portable reasoning to developers, or limit it. That would help against extraction but could make some tools harder to build. Whether hidden reasoning can stay hidden while staying useful is the real open question.