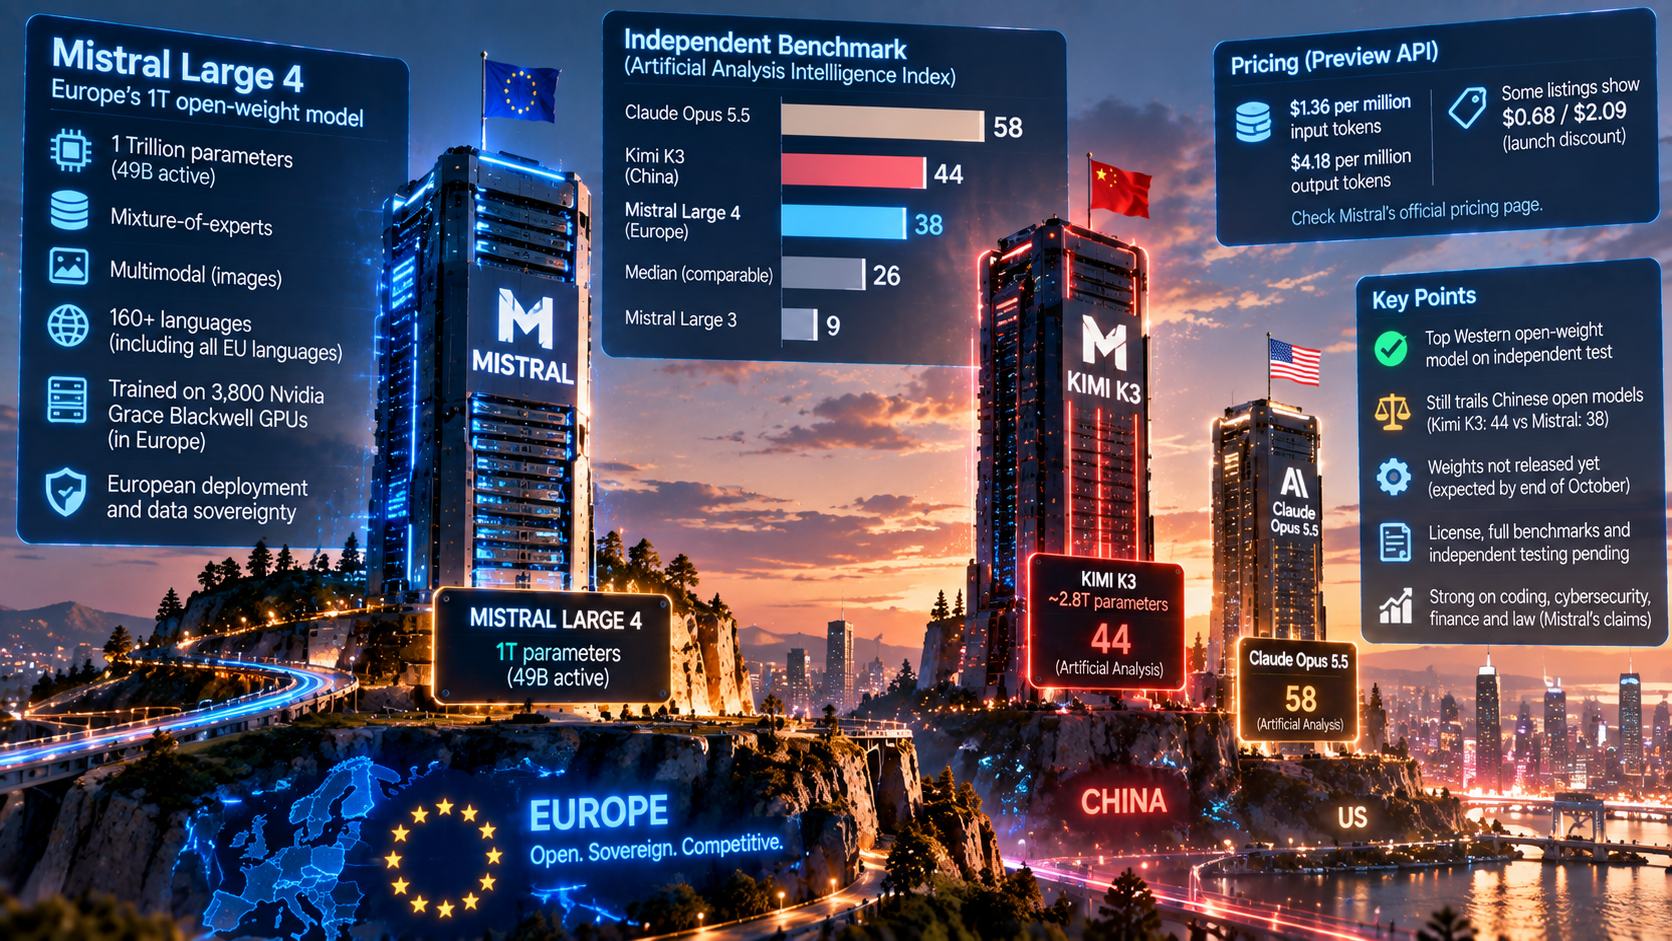
On October 6, 2026, French AI company Mistral previewed Mistral Large 4, a model with about 1 trillion parameters that it plans to release as open weights. It is Mistral's biggest model yet. Mistral says it is far ahead of any open-weight model from the US or Europe. An independent test mostly agrees, but it also shows that Chinese open models still score higher.
There is a catch. Only a preview is out, through Mistral's own API. Mistral says the weights arrive by the end of October, and some reports say October 27. Until then, nobody can download, inspect, or run the model themselves.
What Mistral Built
Large 4 is a mixture-of-experts model. It has about 1 trillion parameters in total, but only 49 billion are active for each token, which is a small chunk of text. Think of a big team where only a few specialists work on each word. The model also reads images, and Mistral says it handles more than 160 languages, including every official EU language.
Mistral says it trained the model from scratch on 3,800 Nvidia Grace Blackwell GPUs in its own data centers in Europe. Some news reports round this to 4,000 chips and say training took about two months. Mistral also serves the preview on that same hardware. It offers a European deployment that it runs itself under European law. This is the sovereignty pitch: a company can keep its data and computing inside Europe, and once it has the weights, it can run the model on its own servers.
Mistral lists the preview API at $1.36 per million input tokens and $4.18 per million output tokens. Some third-party listings show half that, $0.68 and $2.09, which looks like a launch discount. Check Mistral's pricing page before you plan around either number.
Mistral also says its reinforcement learning run, where the model practices tasks and gets scored, is still going. So the model may change before the weights ship.
Claims Versus Measurements
Mistral reports many scores of its own. It says the model is state of the art among open models on cybersecurity, finance, and law. It says it beats GPT-6 Astra on one visual test, 42% to 41%. It also says its top cyber result comes on a test where some closed models refuse the task. These are Mistral's claims. Some use outside tests, but Mistral chose and reported the results.
The cleanest outside number comes from Artificial Analysis, an independent testing firm. Its Intelligence Index combines ten tests. Mistral Large 4 Preview scores 38. That is above the median of 26 for comparable models, and far above Mistral Large 3, which scored about 9. Reports also call it the top Western open-weight model on the chart.
But it does not lead. Kimi K3, from China's Moonshot AI, scores 44. Reports on the same chart put other Chinese open models above Mistral too, and closed leaders such as Claude Opus 5.5 near 58.
Artificial Analysis also found the model wordy. It wrote 200 million tokens during the test, against a median of 81 million, and testing cost $1.13 per task. A low price per token can still add up if a model writes a lot. The firm also revises its index often, so scores from different versions cannot be compared directly.
Why Size Alone Did Not Close the Gap
One trillion parameters is big for a European lab, but it is not the biggest open model. Wikipedia lists Kimi K3 at about 2.8 trillion. More parameters do not guarantee a better model, because training data, tuning, and reasoning also matter. Still, Mistral caught up fast, from about 9 to 38 in one release. A gap of roughly six points to Kimi K3 remains.
What Could Happen Next
In the near term, the weights are due by the end of October. When they land, three things can be checked. First is the license. Mistral Large 3 used Apache 2.0, but Mistral has not published the Large 4 license, so nobody knows yet how freely companies can use it. Second is independent re-testing as training continues. Mistral says it expects large and rapid improvements. Third is size. At 8 bits per parameter, 1 trillion parameters is roughly 1 terabyte of files. That is my own arithmetic, and it means running the model takes a multi-GPU server, not a laptop.
The long-term picture is speculation. If Mistral keeps improving, European banks, governments, and defense firms that want control over their data may pick it even if it scores below Chinese models. If its scores stall, sovereignty alone may not win buyers. The real test is whether control matters as much as the score.