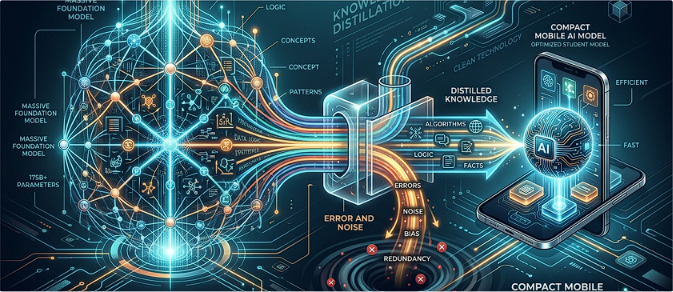
Massive AI foundation models like GPT-4, Claude 3.5, and Llama 3 70B possess impressive reasoning capabilities, but they require massive cloud server farms, hundreds of expensive GPUs, and immense electrical power to run
Investigating Model Compression and Synthetic Data
Computer science researchers at UC Berkeley, Tsinghua University, MIT, and Meta AI set out to investigate the deep trade-offs of knowledge distillation
Experimental Setup: Testing Student Models
To evaluate distilled models, research teams led by Arnab Gudibande (UC Berkeley) and Yuxian Gu (Tsinghua / Microsoft Research) trained small student models across two primary distillation methodologies
-
Off-Policy Imitation Training: Feeding student models static datasets composed of millions of synthetic Q&A responses generated by teacher models like GPT-4
-
On-Policy Distillation (MiniLLM / Reverse-KL): Allowing the small student model to generate its own trial answers dynamically, while receiving continuous mathematical feedback from the teacher model's probability distribution
The researchers benchmarked these compact student models against their foundation teacher models across factual recall, mathematical reasoning (GSM8K), coding logic (HumanEval), and overall hallucination rates
What Researchers Found: The "Imitation Trap"
The experimental findings uncovered a critical vulnerability in standard distillation known as The Imitation Trap
When small student models are trained purely on synthetic text generated by large teacher models, they become highly adept at copying the teacher's tone, formatting, and stylistic confidence
Because small models have far fewer parameters, they lack the raw memory capacity to store the vast world facts that the teacher model relies on
The On-Policy Solution: Cutting Hallucinations by 35%
To break out of the imitation trap, researchers developed On-Policy Distillation (MiniLLM)
By training student models on their own generations rather than passive teacher outputs, researchers achieved major breakthroughs
-
Hallucination Drop: Reduced small model hallucination rates by 35%
-
Reasoning Boost: Increased logical reasoning performance by 22% on standard benchmarks like GSM8K and HumanEval
Limitations: Tail Knowledge Loss and Synthetic Pollution
Despite these algorithmic improvements, fundamental structural limits remain in on-device AI
-
Tail Knowledge Loss: A 3B parameter model running on a mobile phone simply cannot store the long-tail factual knowledge (such as obscure historical dates or specialized medical facts) contained in a 1.75-trillion parameter foundation model
-
Synthetic Data Pollution: If a teacher model contains subtle biases or hallucinations during synthetic data generation, the student model absorbs those errors as absolute ground truth, amplifying mistakes across downstream deployments
Industrial Impact and Next Steps for On-Device AI
Knowledge distillation is essential for privacy-focused, low-latency, on-device AI